

Context Window Scaling vs Semantic Caching: Improving LLM Query Efficiency
So, you're wondering how to make your Large Language Model (LLM) queries faster and more efficient, ...
So, you're wondering how to make your Large Language Model (LLM) queries faster and more efficient, ...
So, can we actually ditch those once-a-year penetration tests and switch to something more like cont ...
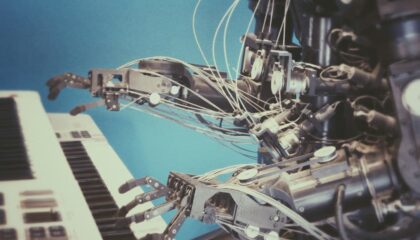
You've probably heard about robots, those metal and plastic machines that do everything from assembl ...
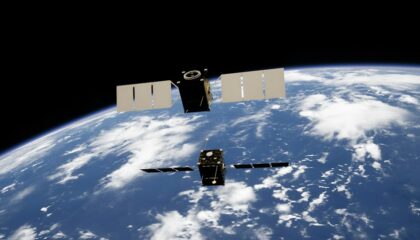
Direct-to-cell satellite connectivity is, put simply, a way for your regular smartphone to connect d ...
So, you’ve been hearing a lot about “liquid staking” in DeFi, and maybe you’re wondering what it is ...
Model drift is a common challenge in production machine learning systems, essentially meaning your m ...
We all know the struggle: you need data to build robust data pipelines, but real-world, sensitive da ...
Hey there! Let's talk about quantum sensing. In a nutshell, quantum sensors are like super-sensitive ...
Let's talk about what's really happening under the hood of modern cars: they're turning into compute ...
So, you're an enterprise looking to get into crypto, or you're already there and wondering how to ...